2015-11-01

Understand the ISO 8601 date format

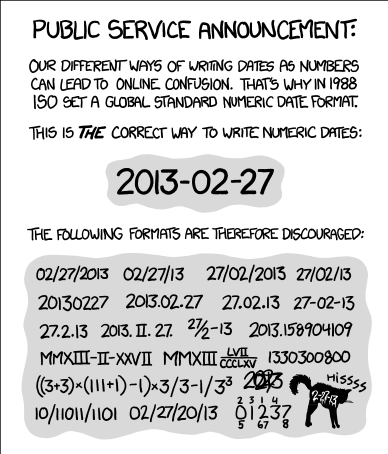
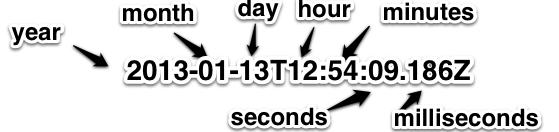
How hard can it be? It seems  to be incomprehensible hard for some to understand the ISO 8601 date format YYYY-MM-DD and acknowledge ISO 8601 as the international standard.
.


One example;  at the company we use Microsoft sharePoint collaborative software. As an american i.e. U.S.A company Microsoft is unaware of ISO standards e.g. date formats are national in sharePoint. The swedish date format in sharePoint is ISO 8601 since we swedes since long have adopted the SI/ISO standard. The US date format is not ISO 8601. The US sharePoint admins at the company are unaware of ISO and do not want to promote the ISO 8601 as default as they believe this is the swedish date format only, instead they use the US date format since they think the US standard is the world standard. If Microsoft could introduce the ISO 8601 as a recognised date format in sharePoint, it would be much easier for me to evangelize the benefits of using one recognised standard format as default for dates in the company. This will probably only happen after the Chinese have established a Chinese hegemony, their date format is sort of big endian in accordance with ISO 8601.


Good reading for programmers

Once in a while you stumble upon a great post, this one by Sean Hickey is also quite fun The evolution of a software engineer.

2015-10-25

Hello SUSE!

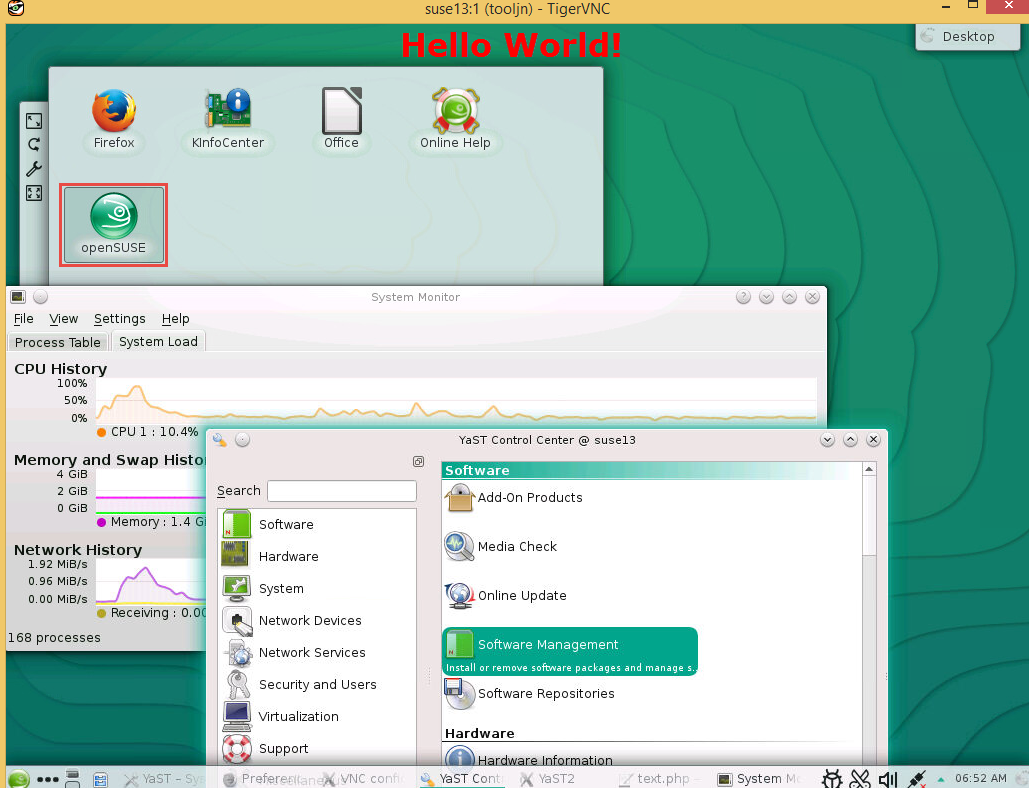
Today I logged on to SUSE Linux for the first time!
First I had to install a vnc server. I logged on with the help of putty and fired up yast in tty mode.
I installed tigerVnc, with yast it was a breeze.


Then I ‘vnc logged into’ SUSE, since it has a KDE gui I felt at home right away.

Now I ‘only’ have to create an ETL server for the Data Warehouse, this will take some time, since I have to do this in my spare time, it is sort of a hobby to me, I do IT architecture during work hours. I will blog about my progress.

2015-10-22

Data Warehouse upgrade

After procrastinated a general upgrade of the Data Warehouse for a long time we now have gone from Ubuntu 12.04 to 14.04. To my great surprise this upgrade seems to have worked well. We also painlessly upgraded MySql from version 5.5 to 5.6. We tried MySql 5.7 but found a number of incompatibilities, so we decided to wait with MySql 5.7 until we have ironed out any problem. We had a moment when we thought we had kissed the japanese DW satellite goodbye, after upgrading the server we restarted the server but it didn’t came up again. We had to wait for the guys in Japan to push the power button. But on the whole it was a smooth transition, about ten or so upgraded servers without any major issues.
After the upgraded Data Warehouse landscape have stabilized, we will also try to move our ETL server from Mageia to SUSE Linux. The Data Warehouse started on Mandrake Linux 2001 and continued on Mandriva and lately on Mageia. These Linux distros have served us well but now we will try SUSE not only for the hell of it, SUSE has a partnership with SAP and that might make the Data Warehouse more acceptable in the company. The sad story is nobody in the company knows what Mageia Linux is which makes the Data Warehouse kind of an oddball. SUSE Linux is more digestible for the IT community in the company. But we will try openSUSE not SUSE Linux Enterprise, after all the Data Warehouse was not formed after the  standard enterprise model.

2015-09-21

Curl and sharepoint authentication

Our sharepoint uses NTLM for authentication, it took me some time to figure that out. I access a sharepoint site from our Linux Data Warehouse environment using curl. Seems like curl can handle NTLM, but this is what curl says about NTLM.  

The NTLM authentication method was designed by Microsoft and is used by IIS web servers. It is a proprietary protocol, reverse-engineered by clever people and implemented in curl based on their efforts. This kind of behavior should not be endorsed, you should encourage everyone who uses NTLM to switch to a public and documented authentication method instead, such as Digest.

curl --ntlm -u userid  http://sharepointServer/thePathTo/Items

2015-09-13

Big O


Recently I came across something that reminded me of my youth, big-O calculations. Big-O is used to calculate the complexity of algorithms or programs, big-O gives you a rough worst case estimation of the performance of an algorithm, and how runtime and space grows relative to the size of the input.
I didn’t know anything at all about big-O, but replied ‘do anyone really do that kind of calculation?’, when I was asked about big-O.  It reminds me of the time when people tried to estimate run times of programs by calculating revolving speed of drum memories and the time of machine instructions etc. When I started work with computers people had just stopped doing that type of calculations, and I was very happy for that.
I was told big-O is a big thing, it gives a worst time measurement of the algorithm the higher big-O figure the likelier it will run slower. But there is so many ifs and buts, these days you cannot do proper run time calculations just by evaluating the source code, you need to understand the program optimizer, high level instructions, libraries, hardware, opsys. If you have a program language good at  e.g. parallel optimize your code with a JIT compiler that may skew your calculations, if I got big-O right.
I have checked with some younger colleagues, one said when I asked, ‘I recall this from school,  but I never used it in real life, real runtime figures are dependent on so many other things, I can image it can be of use for assembler or C programmers, but for modern high level programming languages it is probably of limited use’. The others I asked did not know what big-O was, one said he remembered something about calculating runtime of programs.  
With my limited knowledge, I see big-O as a simple and clever option to programmatically compare different program snippets. This can come handy if you are developing a program language optimizer or a JIT compiler, but otherwise it is of little use. Big-O is an interesting subject and gives food for thought. I would not be surprised if I will use big-O one of these days.


I have spent years of optimizing computer systems, anything from network throughput to assembler algorithms, SQL queries, physical IO of databases etc, etc. I ‘only’ used real measurement, which you can rely on since they are real.    


Links I found useful when I studied big-O:

http://discrete.gr/complexity/
https://www.interviewcake.com/article/big-o-notation-time-and-space-complexity
http://bigocheatsheet.com/

2015-09-02

Summer's (almost) gone

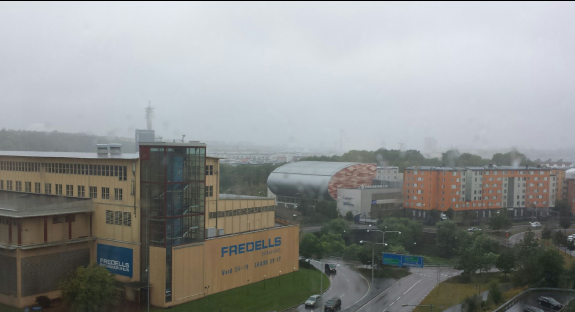
Summer ended 1st September 2015 here in Stockholm. We had a fantastic summerly August which is rare here, most years summer is over in mid August, but not this year.
Autumn view from the office 2nd September, rainy but still warm.


I spent some time this August getting acquainted with MS SQL Server, it was an unexpected pleasant experience. Last time I  looked at SQL Server was 2001 and at that time I disregarded the software as a toy not fit for serious work. That is not true anymore, it looks like a good serious database manager. I have to spend a lot more time with the database to really understand SQL Server, but it was a breeze to create a database with constraints, indexes and all that. The management studio is a nice development environment. Transact-SQL will probably take a long time to master. On the whole SQL server is the same as other mature relational database managers, but different (they all are :-).
While working with SQL server I realised I miss DBA work, real proper DBA work, designing database, fixing performance problems, helping developers with tricky SQL queries. Not only installing the software and running utilities. I have to do something about this :-)